このチャンネルのほかの紹介
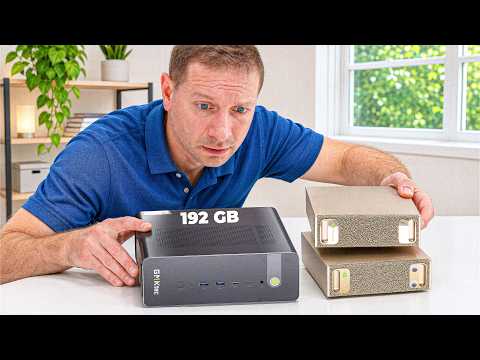
GMK Tech Evo X5 Pro vs NVIDIA DGX Spark: Running 150GB+ LLMs on a Mini PC
This comparison tests whether a single GMK Tech Evo X5 Pro mini PC, equipped with 192GB of unified memory, can…

Does System RAM Matter More Than VRAM for Running Local AI Agents?
System RAM and VRAM both matter for local AI, but they serve different roles, and this test measures exactly w…

Dell XPS 13 vs. MacBook Neo: Local AI on Entry-Level Laptops
A compact comparison examines the base Dell XPS 13 and the MacBook Neo as entry-level machines for local AI ta…
 📺 Tiny AI box vs massive AI workstation. 🚀
Asus GX10 and DGX Station Compared for Running Large Language Models
▼
An overview of two Asus systems designed for local LLM inference: the compact Asus Ascent GX10 with 128 GB of memory and the larger Asus Expert Center Pro ET900 NG3, positioned as a DGX Station with 748 GB. The comparison focuses on which model sizes each machine can run and how throughput changes as parameter counts increase. It also outlines when the smaller unit is sufficient and when the larger system or multiple stacked GX10 units become relevant.
■ Hardware overview
- Asus Ascent GX10 compact unit with 128 GB
- Asus Expert Center Pro ET900 NG3 DGX Station with 748 GB
■ Model testing scope
- Dense and mixture-of-experts models from small to very large parameter counts
- Throughput and capacity limits as models approach or exceed 128 GB
■ Practical selection
- When the GX10 is sufficient and when the DGX Station is needed
- Stacking multiple GX10 units for larger workloads
For viewers assessing local AI hardware, this provides a structured look at capacity, performance trade-offs, and practical selection criteria. It is suited to those comparing compact and workstation-class systems for LLM deployment and wanting a clearer view of which hardware tier matches their model size and speed requirements.
この動画を紹介した Alex Ziskind の最新動画も、紹介付きで読めます。
いつも見ているチャンネルも、同じように紹介できます。
いつも見ているチャンネルを追加する📄 このページの紹介文は AI が独自に生成したものであり、著作権をはじめとする他者の権利(商標権・名誉権・プライバシー等)を侵害しないよう配慮しています。動画の著作権は各作成者に帰属します。